• Skip to main content
  • Skip to primary sidebar
  • Skip to footer
  • Home
  • About Darknet
  • Hacking Tools
  • Popular Posts
  • Darknet Archives
  • Contact Darknet
    • Advertise
    • Submit a Tool
darknet.org.uk logo

Darknet - Hacking Tools, Hacker News & Cyber Security

Darknet.org.uk is a cybersecurity site online since 2000. It covers security tools, technical research and hacking news, alongside an archive of earlier posts.

Hacking News

Our archives contain the very best Hacking News articles including large scale hacks, exploit release, patches, 0-day and coverage of all major hackings.
Hacking News

US Government Cyber Security Still Inadequate

Published June 27, 2019 |

Views: 3,262

US Government Cyber Security Still Inadequate

Surprise, surprise, surprise – an internal audit of the US Government cyber security situation has uncovered widespread weaknesses, legacy systems and poor adoption of cyber controls and tooling. US Government security has often been called into question but we’d hope in 2019 it would have gotten better and at least everyone would have adopted the […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

HTTrack – Website Downloader Copier & Site Ripper Download

Published October 8, 2018 |

Views: 7,455

HTTrack - Website Downloader Copier & Site Ripper Download

HTTrack is a free and easy-to-use offline browser utility which acts as a website downloader and a site ripper for copying websites and downloading them for offline viewing. HTTrack Website Downloader & Site Ripper HTTrack allows you to download a World Wide Web site from the Internet to a local directory, building recursively all directories, […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

Yahoo! Fined 35 Million USD For Late Disclosure Of Hack
Published May 4, 2018 |

Views: 4,410

Yahoo! Fined 35 Million USD For Late Disclosure Of Hack

Ah Yahoo! in trouble again, this time the news is Yahoo! fined for 35 million USD by the SEC for the 2 years delayed disclosure of the massive hack, we actually reported on the incident in 2016 when it became public – Massive Yahoo Hack – 500 Million Accounts Compromised. Yahoo! has been having a […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

MyEtherWallet DNS Hack Causes 17 Million USD User Loss
Published April 29, 2018 |

Views: 5,806

MyEtherWallet DNS Hack Causes 17 Million USD User Loss

Big news in the crypto scene this week was that the MyEtherWallet DNS Hack that occured managed to collect about $17 Million USD worth of Ethereum in just a few hours. The hack itself could have been MUCH bigger as it actually involved compromising 1300 Amazon AWS Route 53 DNS IP addresses, fortunately though only […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

Cambridge Analytica Facebook Data Scandal

Published March 25, 2018 |

Views: 4,469

Cambridge Analytica Facebook Data Scandal

One of the biggest stories of the year so far has been the scandal surrounding Cambridge Analytica that came out after a Channel 4 expose that demonstrated the depths they are willing to go to profile voters, manipulate elections and much more. It’s kicking off in the UK and the US and Mark Zuckerberg has […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

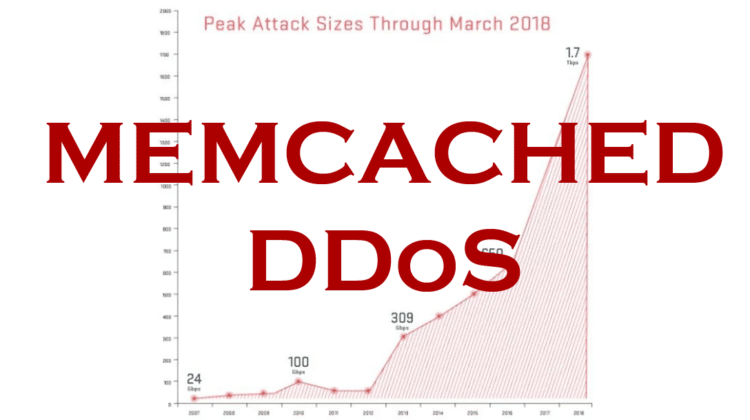
Memcached DDoS Attacks Will Be BIG In 2018
Published March 8, 2018 |

Views: 4,820

Memcached DDoS Attacks Will Be BIG In 2018

So after the massive DDoS attack trend in 2016 it seems like 2018 is going to the year of the Memcached DDoS amplification attack with so many insecure Memcached servers available on the public Internet. Unfortunately, it looks like a problem that won’t easily go away as there are so many publically exposed, poorly configured […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

0-Day Flash Vulnerability Exploited In The Wild
Published February 3, 2018 |

Views: 4,658

0-Day Flash Vulnerability Exploited In The Wild

So another 0-Day Flash Vulnerability is being exploited in the Wild, a previously unknown flaw which has been labelled CVE-2018-4878 and it affects 28.0.0.137 and earlier versions for both Windows and Mac (the desktop runtime) and for basically everything in the Chrome Flash Player (Windows, Mac, Linux and Chrome OS). The full Adobe Security Advisory […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

Uber Paid Hackers To Hide 57 Million User Data Breach

Published November 23, 2017 |

Views: 4,769

Uber Paid Hacker To Hide 57 Million User Data Breach

Uber is not known for it’s high level of ethics, but it turns out Uber paid hackers to not go public with the fact they’d breached 57 Million accounts – which is a very shady thing to do. Getting hacked is one thing (usually someone f*cked up), but choosing as a company to systematically cover […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

Terabytes Of US Military Social Media Spying S3 Data Exposed

Published November 18, 2017 |

Views: 8,534

Terabytes Of US Military Social Media Spying S3 Data Exposed

Once again the old, default Amazon AWS S3 settings are catching people out, this time the US Military has left terabytes of social media spying S3 data exposed to everyone for years. It’s not long ago since a Time Warner vendor and their sloppy AWS S3 config leaked over 4 million customer records and left […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More

Ethereum Parity Bug Destroys Over $250 Million In Tokens

Published November 9, 2017 |

Views: 4,095

Ethereum Parity Bug Destroys Over $250 Million In Tokens

If you are into cryptocurrency or blockchain at all, you will have heard about the Ethereum Parity Bug that has basically thrown $280 Million value or more of Ethereum tokens in the bin. It’s a bit of a mess really, and a mistake by the developers who introduced it after fixing another bug back in […]

Share
Tweet
Share
Buffer
WhatsApp
Email
Hacking News› Read More
  • « Go to Previous Page
  • Page 1
  • Page 2
  • Page 3
  • Page 4
  • Interim pages omitted …
  • Page 24
  • Go to Next Page »

Primary Sidebar

Search Darknet

Advertisement
  • Email
  • Facebook
  • LinkedIn
  • RSS
  • Twitter

Advertise on Darknet

Latest Posts

http-terminator — AI-ASSISTED HTTP REQUEST SMUGGLING DISCOVERY; two offset request boundaries in parallel channels; darknet.org.uk.

http-terminator – AI-Assisted HTTP Request-Smuggling Discovery

Views: 373

http-terminator is a research pipeline from PortSwigger that points a large language model at HTTP specifications and asks it to find request-smuggling attacks. It was published alongside the research it produced, as a reference companion rather than a product.

http-terminator — AI-ASSISTED HTTP REQUEST SMUGGLING DISCOVERY; two offset request boundaries in parallel channels; darknet.org.uk.

I read the current repository rather than the write-ups about it. What’s there is a four-stage pipeline: two stages are self-contained, and two need Burp, the last of them also a simulator the repository doesn’t ship.

At a check on 27 September, the public main branch contained one commit, 874682c, dated 22 July 2026.

The ground this sits on

A 2017 post here on Microsoft’s Azure web application firewall mentions request smuggling among the attacks a WAF blocks, but doesn’t explain it, so it’s worth a sentence. Request smuggling – also called desync – exploits a disagreement between two servers about where one HTTP request ends and the next begins.

Put a front-end proxy in front of a back-end server and send a request the two parse differently, and the back-end can treat part of your input as the start of another request. In one variant, response poisoning, the next user’s request on that reused back-end connection completes your smuggled prefix, and that user receives the response to your request instead of their own. PortSwigger researcher James Kettle has published techniques and research on it.

From specifications to test cases

PortSwigger’s own HTTP Request Smuggler tests targets from Burp Suite and includes a research mode for exploring new desync techniques. http-terminator takes a document-driven approach: Claude extracts candidate vectors from specifications, which feed generation, validation and investigation stages.

The four stages

The pipeline runs in four stages:

  • seeker (Python) reads documents and RFCs and, through Claude, extracts candidate desync vectors.
  • flamer (Java) turns those vectors into malformed HTTP test-cases.
  • validator, a Burp extension, fires the generated requests at a target and reports confirmed desync findings and unconfirmed anomalies.
  • investigator (Python, driven by Claude Code) replicates the hits, confirms them, chases follow-on impact and writes them up.

Reproducing it is where the documentation gets tangled. seeker and flamer are self-contained – Python or Java, plus an Anthropic API key. The other two are not.

The validator’s documentation needs careful reading. The root README lists commercial Burp Suite for running it, while the validator’s own README says its test suite runs under Burp Community or Professional, with the Professional-only tests skipped on Community. Those cover different things, running the stage and testing it. Where the repository does contradict itself is the build: the validator’s README says the build depends on bulkScan-all.jar and that the jar is not vendored in the repository – yet it is committed at validator/bulkScan-all.jar, and the build file points at it. investigator, in turn, needs an external MCP simulator and Burp Organizer alongside Claude Code and a live target.

Following the data through the stages

Start in seeker/, with Python 3.11 or later, an Anthropic API key and network access. The README installs the package from that directory:

1
pip install -e ".[dev]"

That installs seeker’s command-line tool. Its next command reads a URL list you create, a text file of the document URLs to process, fetches those documents and stores the extracted sections in seeker.db. The repository ships a sample list at seeker/fixtures/urls.txt you can point at instead to try it:

1
seeker process --input urls.txt --db seeker.db --manifest run.manifest.json --verbose

The manifest records that run, while the SQLite database holds the sections you can inspect with seeker’s query command:

1
seeker query --db seeker.db --type http_desync_vector

That selects the extracted desync-vector sections; once flamer has generated requests, seeker can trace a request ID back to its source:

1
python3 -m seeker.cli trace 1002368 --db seeker.db --flamer-db ../flamer/production.db

Replace 1002368, the README’s example, with a request ID from your own flamer database; the trace links a generated request to the seeker section it came from.

Next, from flamer/, with Java 21, Gradle and an Anthropic API key, the default run reads unprocessed sections from ../seeker/seeker.db and writes generated requests to its own production.db:

1
2
export ANTHROPIC_API_KEY=your_key
./gradlew run

The key is required for Claude; flamer’s README also offers a run that does not save generated requests:

1
./gradlew run --args="--dry-run"

Use the documented dump option to view requests already held in flamer’s database:

1
./gradlew run --args="--dump"

Flamer’s Gradle task copies its generated database into the validator directory:

1
./gradlew copyDbToValidator

From validator/, the README builds the Burp extension jar with:

1
./gradlew jar

The documented output is build/libs/validator.jar; load it in Burp via Extensions > Installed > Add and select that file.

That manual extension-loading step is separate from the validator’s livetesting suite, which can use Burp Community or Professional: Community skips the Professional-only tests, while Professional runs them. The root README’s commercial-Burp requirement describes running the validation stage, not this test suite.

There is no investigator command to copy from its README. It calls for Claude Code with an Anthropic API key, an external simulator exposing turbo-simulator MCP tools, Burp Suite and a Burp Organizer-style findings source, plus a target you are authorised to test; those external pieces are not supplied with the repository.

seeker fetches the documents you list and calls Claude; flamer calls Claude and keeps its database local unless you opt into its upload flag. The generated requests are not sent to a target by those two stages. Validation is the point where Burp and target authorisation become necessary.

Authorisation note

http-terminator’s validation stage sends malformed requests designed to desynchronise real servers. Run it only against systems you own or are explicitly authorised to test. Request smuggling can corrupt other users’ traffic on a shared front-end, so an unauthorised test is not a harmless probe, and the repository’s own ethics note says the same.

What it’s worth if you can’t run all of it

What the repository exposes is the design. The tree holds the prompts seeker uses to pull candidate vectors from a specification and the code flamer uses to turn those vectors into test cases. PentestGPT now runs a testing pipeline itself, driven by Claude Code or Codex; http-terminator instead points a model at one class of bug, starting from specifications.

Read that way, the repository is a worked, inspectable design for pointing a language model at a specification to generate desync test cases. Reading it is not the same as confirming it works. That would need running the pipeline against authorised targets, which this article did not do, so nothing here measures how well the approach performs.

I read the repository and its READMEs on 16 September 2026, at main commit 874682c, dated 22 July 2026. Everything above is read from the repository and its GitHub page; I did not run the pipeline.

You can find http-terminator here: https://github.com/PortSwigger/http-terminator

Hash Identifier Tools — Command-Line Password Hash Identification, with one data specimen sorted into several candidate paths; darknet.org.uk.

Hash Identifier Tools – Command-Line Password Hash Identification

Views: 575

I tested hashID 3.1.4 and Name-That-Hash 1.11.0 against the same hash samples. Both recognised $2a$ bcrypt but rejected the otherwise identical $2b$ sample. Only Name-That-Hash recognised the Argon2id sample.

Hash Identifier Tools — Command-Line Password Hash Identification, with one data specimen sorted into several candidate paths; darknet.org.uk.

Both tools were installed through pip and tested on 6 September 2026.

Two others worth knowing, haiti and hashcat, are at the end as alternatives. I didn’t run those, and I say so where they appear.

Different formats, the same hexadecimal shape

Start with the MD5 of the word password, a bare 32-character hexadecimal string. Ask hashID what it is, and it returns eighteen possibilities; ask Name-That-Hash and it returns twenty-four. Both are right to.

MD5, NTLM, LM, MD4, the Domain Cached Credentials formats and a dozen others all produce exactly 128 bits of hex, and nothing in the string itself separates them.

Take a concrete case. The empty LM hash constant aad3b435b51404eeaad3b435b51404ee – the value that fills the LM field of a Windows credential dump whenever the LM hash is blank – produces the same shapeless list from both tools, headed by MD5 and NTLM.

Both tools returned candidate lists for this sample rather than identifying it specifically as the empty LM constant. For the common hexadecimal formats, an identifier narrows the field and then hands the real decision back to you.

Provenance – which system produced the hash, which file it sat in – resolves what the string cannot. So the identifiers earn their keep on formats that carry a self-describing prefix, and that’s where they start to differ.

The 2026 blind spot both common tools share

bcrypt hashes announce themselves with a version prefix. Give both tools a classic $2a$ bcrypt hash, and both identify it correctly – hashID offers bcrypt alongside its two aliases, Name-That-Hash the same. Now change the a to a b in the prefix, making it $2b$ and leaving everything else identical:

1
2
3
4
5
$ hashid '$2b$10$N9qo8uLOickgx2ZMRZoMyeIjZAgcfl7p92ldGxad68LJZdL17lhWy'
[+] Unknown hash
 
$ nth -t '$2b$10$N9qo8uLOickgx2ZMRZoMyeIjZAgcfl7p92ldGxad68LJZdL17lhWy'
No hashes found.

Both fail. $2b$ isn’t an exotic variant. Python’s maintained bcrypt library generates $2b$ by default, so passwords hashed through that path today land in this form unless the caller overrides the prefix.

Two different identifiers, both a single pip command away, and neither recognises a current bcrypt prefix while both handle the older $2a$.

The reported bcrypt results use a 60-character sample; the earlier malformed sample was excluded.

Where the two identifiers diverge

They part company on Argon2, the algorithm that won the Password Hashing Competition and that current guidance names first for new password storage. Given an Argon2id string, hashID returns Unknown hash; Name-That-Hash returns Argon2id. That’s the clearest difference in capability between them.

hashID’s pattern table hasn’t changed since 2015. In this test, it missed both $2b$ and Argon2id; Name-That-Hash recognised Argon2id but shared the $2b$ miss.

The $2b$ prefix dates from 2014, before hashID’s March 2015 release, so it’s a gap the tool never covered, not one that opened up under it. Argon2id does post-date it, and the frozen table is the obvious explanation for that miss.

On the MD5 sample, Name-That-Hash also returned the longer list, twenty-four against hashID’s eighteen, though that’s one input and not a census of either tool’s rules. Of the two, it’s the better-informed on this set. But more maintained isn’t the same as complete: the $2b$ gap belongs to both.

Other maintained options, not tested here

Two more tools are worth knowing, and both were outside what I could run here – the environment had neither a Ruby runtime nor a hashcat build. So what follows is drawn from their documentation and source, not from a test. Read it as a pointer, not a result standing alongside the two above.

haiti is a Ruby identifier that’s actively developed, with a v4 release in early 2026 and recent commits. Its documented draw is that it returns the matching hashcat and John the Ripper references beside each candidate, which is the detail you want if identification is a step toward cracking.

It installs as a gem rather than through pip. Whether it clears the $2b$ bar that both tested tools failed is exactly the claim I won’t make without running it.

And if the next step is a crack, identification may not need a separate tool at all. hashcat carries an --identify option, documented in its own usage text as showing all supported algorithms for an input hash.

Asking hashcat directly removes a translation step between an identifier’s naming and hashcat’s mode numbers. That option is in hashcat’s source; I didn’t run it here.

What to actually use

When Darknet covered hashID in 2017, the page already noted it hadn’t been updated since 2015. This comparison asks whether moving to a maintained identifier closes that gap. For $2b$, it doesn’t.

For a quick look at a hash you already have context for, either pip-installable identifier is fine, and Name-That-Hash is the better-informed of the two: it knows more recent formats, and it’s still maintained. Keep hashID’s limits in mind – this site’s closer look at hashID lays out the full extent of its 2015 freeze.

If you’re working toward a crack, let hashcat identify the hash it’s about to attack. And if identification is a recurring part of your workflow, haiti’s cracker-reference output is worth the gem install.

Tested 6 September 2026. hashID v3.1.4 and Name-That-Hash 1.11.0 were run against a fixed hash set; haiti and hashcat were not run in this environment, and their behaviour is cited from documentation and source, as noted above.

whitelist-bypass — WebRTC Tunnels Through Video Calls, showing one orange media route passing an allowlist gate; darknet.org.uk.

whitelist-bypass – WebRTC Tunnels Through Video-Calling Platforms

Views: 670

whitelist-bypass tunnels internet traffic through commercial video-calling platforms, aimed at networks that permit an approved list of domains and block everything else. Tunnelling over WebRTC isn’t new. What caught my attention is what this project chooses to ride.

whitelist-bypass — WebRTC Tunnels Through Video Calls, showing one orange media route passing an allowlist gate; darknet.org.uk.

Whitelist censorship is a different problem from a blocklist. A blocklist leaves the rest of the internet reachable, so a proxy on some unremarkable host usually gets you out.

A whitelist inverts that. Only approved destinations resolve and connect; everything else fails. To get through, your traffic has to be one of the approved destinations, not merely look unlike a blocked one.

whitelist-bypass’s answer is to send your data to a video-calling service the censor has already allowed. A device on the censored network places what looks like an ordinary call to VK Call, Yandex Telemost, or WB Stream; a machine on the free internet answers, and the traffic you actually want rides inside that call.

It all rests on the platform’s media server sitting on the approved list. Whether a given platform is permitted, and stays permitted, is a fact about one network at one moment. The tool doesn’t control it.

Two tunnels, and why there are two

The project gives you two ways to carry data through the call, and the second one exists because the first can be throttled.

DC mode opens a WebRTC data channel – an SCTP stream, the same primitive a browser uses for peer-to-peer file transfer – and pushes a SOCKS5 tunnel through it. Your traffic becomes data-channel payload, relayed by the platform’s media server like any other call data.

Video mode does the same job, but encodes the data onto a published VP8 video track instead. It’s there for a reason the repository makes clear: some media servers rate-limit data channels while passing video freely, and on at least one supported platform the publisher’s track has to be video at all.

So when the data channel gets squeezed, the tunnel moves into the one stream a video call can’t do without. Both modes share the same framing and multiplexing above the transport, so the only difference is which stream carries the bytes.

The recommended deployment runs headless on both ends: pure Go on the Pion WebRTC stack, talking to the platform’s media server directly with no browser in the loop.

What is actually in the repository

I cloned the current main branch (commit 747f8f2, 3 September 2026) and read the source rather than the description of it. The tunnel is real code, not a README promise.

The shared relay under relay/ implements the SOCKS5 proxy, the data-channel and VP8 tunnels, a connection multiplexer and an obfuscator. Separate headless creators handle each platform – vk, telemost, wbstream and dion – each its own Go module that creates or joins a call through the platform’s API without a browser.

The obfuscator is a deliberate choice. It derives a secret from the call’s join link, hashes it with SHA-256, and uses that key with XChaCha20-Poly1305 authenticated encryption and random per-message nonces; it also pads keepalive frames.

So the payload inside the call is encrypted independently of the platform’s own transport security, keyed by something both ends already share: the link used to join the call. Any smoothing of the video track’s timing is separate transport code, not part of the obfuscator.

It’s genuinely multi-platform. The joiner – the client on the censored side – targets Android, iOS and Linux; the creator, on the free side, targets Windows, macOS and Linux. On Android it runs as a system VPN, so all traffic flows through the call.

iOS is more involved. The source tree carries two forms: a proxy app that exposes a local SOCKS5 endpoint another app points at, and a VPN app that uses Apple’s Network Extension capability for system-wide routing.

Only the proxy build ships as a prebuilt IPA in the v0.3.8 release. The VPN app is in the source and its build target is documented, but it needs signing and that capability, so if you want it you’ll be building and signing it yourself.

Build documentation note

If you build from source, do not follow the README’s build table exactly. It lists ./build-app.sh for the Android app; that script is not in the repository. The scripts that exist are build-android.sh, build-joiner-app.sh, build-go.sh, build-headless.sh and the rest. Prebuilt Android, iOS and desktop binaries are on the Releases page and are unaffected; it is the source-build instructions that have drifted from the code.

Where it sits among WebRTC tunnels

Carrying a tunnel over WebRTC is well-trodden ground. Pion’s own ecosystem list includes Tor’s Snowflake, weron, rtctunnel and a WebRTC socket proxy, and whitelist-bypass sits on that same list. So the interesting part isn’t the transport but the carrier it rides.

Snowflake, the closest well-known relative, uses volunteer browsers as ephemeral WebRTC proxies to reach Tor. whitelist-bypass instead points at named commercial calling services and leans on them being individually whitelisted by the censor.

That’s a sharper bet, and a more fragile one. It works precisely because a specific platform is on the approved list, and it stops working the moment that platform comes off it. The video-track fallback is the same logic one level down: when the cheap channel is squeezed, you move to the stream the service can’t throttle without breaking the calls it exists to carry.

Darknet has covered the covert-tunnel idea before, from the enterprise side. ProxyBlob runs a SOCKS5 tunnel over Azure Blob Storage, betting that a cloud endpoint is too ordinary to block. whitelist-bypass makes the same structural move against a stricter filter, with a consumer platform as the cover instead of a cloud service.

The claim to be careful about

The project says that to deep-packet inspection the tunnel “looks like a normal video call”. That’s the load-bearing claim, and it’s the one this article can’t verify.

So does it actually look like a video call on the wire? Confirming that needs a real censored network, live DPI equipment, and traffic analysis over time, none of which a source review gives you.

There are reasons for genuine caution. A real video call has a characteristic traffic shape: bitrate, packet timing, the rhythm of a codec reacting to a moving image. A tunnel that’s pushing bulk data through a VP8 track is under pressure to depart from that shape.

The project does offer configurable VP8 pacing and padded keepalive frames, controls plainly aimed at the problem. But whether the result survives statistical traffic analysis, rather than simple protocol matching, is an empirical question and an arms race. It isn’t a property you can read off the code, so I’d treat “looks like a video call” as the project’s design goal, not a measured result.

Two smaller cautions follow from the design. It depends entirely on the carrier platform staying whitelisted, so it’s only ever as durable as that political fact. And the obfuscator keys on the join link, so a session is only as secure as that link’s distribution: anyone who has the link has the key.

Maturity and provenance

The repository is MIT-licensed, sits at around 1,630 stars and 100 forks, and is actively developed: seventeen releases, the most recent (v0.3.8) in July 2026, commits running into September, six contributors led by one. That’s real momentum for a project barely six months old.

The 0.3.x version line is honest about where it stands, too – software shipped through release artefacts and still changing, not a settled release.

There’s one practical consequence of the anti-censorship purpose. The project’s public contact is a Telegram channel rather than a corporate page, and its authorship is a handful of pseudonymous GitHub accounts. For a tool whose users may be on the wrong side of a national firewall, that’s unremarkable.

It does mean, though, that the repository points at no named organisation, no identified maintainer and no published security audit. Anyone deploying it for real is trusting the code and the build, and should read both.

Reviewed 6 September 2026 against commit 747f8f2. I verified the source-level mechanism, build surface, release history and dependency choices directly; I didn’t run it against a live target, and its DPI-resistance claim is the project’s own, not independently confirmed here.

You can find whitelist-bypass here: https://github.com/kulikov0/whitelist-bypass

WRAITH browser hook and Page Mirror concept

WRAITH – Browser Hooking and Blind XSS Page Mirroring

Views: 802

WRAITH is a browser-hooking framework that combines a BeEF-style command channel with the evidence collection normally associated with tools such as xsshunter-express. A JavaScript hook calls home over WebSocket, appears in an operator console and can receive capture, social-engineering and local-reconnaissance modules.

WRAITH browser hook and Page Mirror concept

The public repository appeared on 1 August 2026. Its three commits all landed that day: the initial code release, a metadata correction and a documentation update. The package declares version 1.0.0, but there is no GitHub release and the project describes itself as work in progress.

Darknet first covered BeEF in October 2006, when its modular console and list of controlled browsers were the story. BeEF still uses a hooked browser as a beachhead for command modules. WRAITH keeps that model, adds the one-shot evidence expected from blind-XSS tooling, then tries to make the captured page navigable.

The hook itself is small enough to follow. It derives its callback address from the script URL, connects to the public /ws/hook endpoint and sends a browser fingerprint. The operator can deploy JavaScript modules to that live browser; completed results return over the same channel and are persisted by the server.

Page Capture fires automatically by default. It records the origin, URL and referrer, reads JavaScript-visible cookies, serialises the DOM and attempts a screenshot. The implementation labels the two important failures instead of hiding them: HttpOnly cookies are unavailable to JavaScript, while Content Security Policy or cross-origin images can prevent a useful screenshot.

Page Mirror takes a different route. When the operator follows a link, the command is relayed to the hooked browser. That browser calls fetch() with credentials included, reads the response and sends the returned HTML back to WRAITH. The request therefore carries cookies that JavaScript cannot read directly, including an HttpOnly session cookie, because the browser attaches them to an eligible same-origin request.

HttpOnly still does its job: the cookie value is not exposed to the hook. It does not prevent code already executing in the origin from asking the browser to make an authenticated request. WRAITH makes that distinction visible in its practice lab, where the captured cookie list is empty but a mirrored request can still reach a session-gated page.

The operator is not remotely driving the victim’s original tab. WRAITH removes scripts from the returned HTML, inserts a base URL, intercepts link clicks and blocks form submissions inside a sandboxed frame. Each selected link becomes another credentialed GET request through the hooked browser.

A server-rendered application with useful links can become a navigable evidence set. A client-heavy application whose interface depends on JavaScript will not replay faithfully, and a workflow that requires a form submission is deliberately stopped. Calling it a mirror is fair; treating it as a complete remote-browser session is not.

For a red-team engagement, the useful sequence starts after authorised JavaScript execution has already been achieved. Page Capture establishes where a blind payload fired. Page Mirror can then inspect same-origin pages available to that browser session without first extracting the session token. Cross-origin reads remain subject to the browser’s Same-Origin Policy.

What was tested

I cloned the current main branch, installed the locked Node dependencies and started WRAITH on loopback. The operator console, demo page, practice lab and hook script each returned HTTP 200. All twelve JavaScript files passed Node’s syntax checker.

The public-bind safeguard also behaved as documented. Starting the server on 0.0.0.0 without an operator password exited with status 1 and refused to expose the console. I did not connect a second browser, deploy an overlay or exercise Page Mirror against anything outside the bundled local lab.

Maturity note

WRAITH has one contributor and no test command in package.json. The repository had 137 stars and 12 forks when reviewed on 1 September 2026, but those counts do not establish operational use. Its code has not changed since the initial public commit.

Installation

The documented Docker route requires Node.js 18 or later, Docker and Docker Compose. The repository’s setup sequence is:

1
2
3
git clone https://github.com/Arcanum-Sec/wraith
cd wraith
./setup.sh

setup.sh asks for the public address and operator credentials, generates a session-signing secret, writes a protected .env file and starts the container. A local development route is also documented with npm install followed by npm start.

The service refuses a public bind without an operator password, but the hook endpoint must remain reachable by design. A real deployment therefore needs more than a password: the project’s deployment guide recommends TLS, a per-cohort credential and removing the service between exercises.

The server becomes part of the evidence boundary

WRAITH persists captured credentials, DOM content, scan results and mirrored page HTML under data/sessions.json. It keeps as many as sixty mirrored pages per session and caps stored HTML at two megabytes per page. Hiding a session in the console does not delete it; the operator has a separate permanent-forget action.

That makes the WRAITH host sensitive even in an authorised exercise. The data directory can contain the same application content and credentials the engagement was intended to demonstrate. Retention, access control and teardown belong in the test plan before the first payload is delivered, not after the console has collected evidence.

WRAITH is not a BeEF replacement yet

BeEF has accumulated thousands of commits, an extension system and a large catalogue of command modules. WRAITH currently ships a much smaller set: three login overlays, page capture and a browser-based port scanner alongside the mirror. The comparison is useful because it shows the design lineage; it does not establish feature parity.

Blind-XSS tooling usually proves that a payload executed and returns a snapshot. A classic browser hook supplies an interactive command channel. WRAITH joins those stages and adds credentialed, same-origin link traversal without claiming that it has stolen an HttpOnly cookie.

That boundary is not new. Darknet covered evilreplay in July 2025: it also uses JavaScript already running in an origin to act through an authenticated browser session without reading the cookie value. The difference is operational. evilreplay aims at interactive post-exploitation control, while WRAITH’s Page Mirror deliberately narrows the job to credentialed same-origin GET traversal, strips scripts and blocks forms. WRAITH packages that traversal beside blind-XSS capture and a persistent module channel; it does not establish a new session-riding mechanism.

The unresolved part is browser behaviour over time. WRAITH’s own network-scanning notes already distinguish reliable loopback checks from LAN modes affected by newer browser controls. Page Mirror depends just as directly on fetch behaviour, session policy and the shape of the application being mirrored. With no automated test suite and no code revision since launch, those boundaries still need to be exercised on the browsers and applications an engagement actually uses.

Download WRAITH and inspect the source on GitHub.

Praetorian, Portable Go Offensive Security Tools, beside a modular toolchain illustration with the darknet.org.uk watermark.

Praetorian – Offensive Security Tools Built Around Portable Go Workflows

Views: 937

Praetorian’s Roman names suggest a coordinated offensive security suite. The repository dependency graph shows a looser and more useful structure: independently installed Go tools, several direct workflow connections, and a shared SDK used by part of the collection

Praetorian, Portable Go Offensive Security Tools, beside a modular toolchain illustration with the darknet.org.uk watermark.

In the ten repositories assessed on 9 August 2026, four imported capability-sdk: Brutus, Pius, Vespasian and Trajan. The other six did not. Brutus also imported Nerva directly, while Aurelian imported Titus. The shared SDK arrived after the tools it now connects.

That result sets the boundary. These projects cover familiar parts of an assessment, including service fingerprinting, credential testing, secrets scanning, asset discovery, API assessment, Bluetooth Low Energy testing and cloud security. They fit Darknet’s Hacking Tools coverage, but a Roman name alone says nothing about whether two tools exchange data or share an implementation.

The strongest case for the collection appears where Praetorian has reduced deployment work or removed translation between stages.

Titus packages secrets scanning for several environments

Titus is a secrets scanner with 487 detection rules drawn from NoseyParker and Kingfisher. It can inspect source trees, Git history, container images, archives and documents, then validate supported credentials against their source services. The same detection engine is exposed through a command-line tool, a Go library, a Burp Suite extension and a Chrome extension.

Its build options also show what “portable” means in practice. The accelerated build uses Hyperscan or Vectorscan through CGO, while a pure-Go target remains available for systems where those native dependencies are unsuitable. The current source instructions build it with:

1
make build

The output is written under dist/titus. Prebuilt releases are available as a separate route. Those are the installation claims the repository supports; its Vectorscan clone command installs a build dependency, not Titus itself.

Titus therefore consolidates detection, file handling and credential validation behind one interface. The rule count does not establish coverage by itself, and successful validation proves that a credential works at the time of the check, not what access its owner intended. Those questions still belong in the assessment around the tool.

Nerva and Brutus form the clearest pipeline

Nerva fingerprints more than 170 protocols across TCP, UDP and SCTP. It expects another scanner to find open ports, then identifies the services behind them and emits structured results. Checks for common service misconfigurations require an explicit option and are absent from its default fingerprinting pass.

Brutus consumes those results and tests credentials across 27 protocols. Its documentation includes a complete pipeline from network discovery through service identification to credential testing:

1
naabu -host 10.0.0.0/24 -silent | nerva --json | brutus creds -P passwords.txt

On an authorised assessment, that command lets Naabu identify exposed ports, Nerva determine what is listening, and Brutus apply an agreed password set to the relevant services. This is the collection’s most concrete integration: Brutus imports Nerva, and the documented data path removes a parsing step between them.

The Brutus name also collides with Darknet’s own archive. Brutus AET2 appeared here in 2006 as a Windows remote login cracker, while THC Hydra followed in 2007. Praetorian’s Brutus addresses the same broad job with a maintained Go binary and an input path from current discovery tooling. The shared name does not indicate a relationship between the projects.

Caeruleus consolidates a fragmented Bluetooth workflow

Caeruleus applies the same engineering approach to Bluetooth Low Energy assessments. Its documentation starts from a workflow split across bettercap, deprecated BlueZ utilities and custom Bleak scripts. Caeruleus combines discovery, interaction and assessment functions in one Linux binary, with JSON and JSONL output for later processing.

This is useful consolidation because the underlying task normally crosses several utilities with different interfaces. It is still bound to Linux, compatible Bluetooth hardware and the operating system’s Bluetooth stack. One binary reduces setup without removing those environmental constraints.

The remaining repositories spread across other stages of an engagement. Pius maps organisations to internet assets, Vespasian discovers API surfaces, Hadrian tests API authorisation, Augustus targets large-language-model applications, and Aurelian examines cloud environments. They need to be assessed against the established tool in each category; their common authorship and implementation language do not supply that comparison.

The shared SDK marks a partial product boundary

Praetorian describes capability-sdk as a shared Go SDK for building security capabilities for the Guard platform. It supplies common Target, Finding and Capability types. Its architecture diagram shows a “Chariot Adapter” in a separate chariot repository. Both the Guard and Chariot names appear in the project’s own documentation; the public material does not explain the difference.

The four imports measured on 9 August establish a real integration layer, with six assessed repositories still operating outside it. Direct dependencies add another layer: Brutus uses Nerva, and Aurelian uses Titus. This produces a partially connected collection in which some tools can run independently, some hand work directly to another repository, and some can also emit types intended for Praetorian’s platform.

That architecture leaves a practical test for each project. A portable binary matters when it removes installation work on an engagement system. Structured output matters when another stage actually consumes it. A replacement matters when it preserves the coverage and reliability of the incumbent while reducing operational friction. The Nerva-to-Brutus path demonstrates all three properties; the other repositories have to demonstrate them in their own domains.

Browse Praetorian’s open-source repositories: https://github.com/orgs/praetorian-inc/repositories

AI IR Overlay — Incident Response for AI Agents, with agent, identity, tools, memory, kill_switches, evidence_export and $ python3 scripts/validate.py --strict.

AI IR Overlay – Incident Response Specification for AI Agents

Views: 821

An OAuth token can be valid, the API call authorised, and the action still be something nobody intended. The agent used the credential it was given, through the interface it was approved for, and the audit log records all of it correctly. Nothing in that sequence resembles an intrusion, because nothing was intruded upon.

AI IR Overlay — Incident Response for AI Agents, with agent, identity, tools, memory, kill_switches, evidence_export and $ python3 scripts/validate.py --strict.
AI IR Overlay extends established incident-response practices with AI-agent inventories, graded containment, evidence capture and controlled recovery.

That is the case AI IR Overlay is built around, and it is a genuinely awkward one for an incident response programme. There is no compromised account to disable. Identity telemetry is accurate and unhelpful. The question is not whether the credential was stolen but what the agent was told, what it could reach, and how much of that it did before anyone noticed.

The framework is a specification for answering those questions: 24 playbooks, three JSON schemas, two runnable reference implementations, Apache 2.0, one author. It is better than its adoption numbers suggest, and it stops in a specific and interesting place.

What it actually supplies

Three artefacts, mapped onto NIST SP 800-61 Rev. 3 and cross-referenced to NIST CSF 2.0, the NIST AI RMF and the OWASP Top 10 for Agentic Applications.

An AI Bill of Materials — YAML, one per production agent, recording service identity, scopes, tools, write targets, memory settings and retrieval sources. The insistence throughout is on what the deployed agent can reach rather than what the design document says it should. An agent wired into email, a CRM and an ERP has three separate blast radii before anyone has looked at the model, and that map costs far less to build on a quiet Tuesday than at two in the morning.

A containment ladder, M0 to M5, replacing the single kill switch. M1 is the rung that matters: “All write tools are stripped from the agent’s tool set”, with read and query tools left running. That is the containment shape you actually want for an agent sitting inside a business process, because destroying the session and rotating every credential also destroys the state needed to reconstruct what happened.

A minimum evidence set across six classes — prompts and responses, tool-call records, retrieval traces, memory state, configuration state, and identity or downstream audit logs. Wider than endpoint telemetry by design, because the opening case produces no unusual process tree and no suspicious authentication event.

None of this asks a SOC to invent a new discipline. The command structure, the evidence handling and the recovery process all stay where they are, which is the framework’s best decision and the reason it is worth the reading time.

What the validator proves

scripts/validate.py is 279 lines. It performs JSON Schema validation and date-staleness checks against the AI-BOM and privilege-matrix files — no subprocess call, no network access, nothing that executes the systems being described.

That is more useful than it sounds. A containment-test date that has gone stale becomes a build finding, which is more than most control frameworks manage. Two qualifications matter, though, and both are easy to overstate in the other direction.

Staleness only fails a build in strict mode. By default the validator prints STALE-WARN and exits zero; --strict turns those into errors. A team wiring this into CI without the flag gets warnings the pipeline does not enforce.

And a passing build says a control was declared, not that it works. The validator confirms an organisation has written down that it has a kill switch and written down when it last tested one. Whether the switch functions is outside what any schema check can reach. That distinction is the whole subject of this framework, so it is worth not blurring in the one place it can be measured.

Where the automation stops

The actuation layer is more complete than a quick look suggests. There is a 19KB kill-switch API contract in schemas/kill-switch-api.md, referencing M1 a dozen times, and a runnable demo in reference-impls/kill_switch_demo/ implementing the M0–M4 contract against a synthetic tool registry — M5, controlled re-enable, is explicitly out of scope. A second reference implementation, evidence_exporter, ships adapter stubs for each of the six evidence classes. The interface for moving an agent between containment states is specified and demonstrated.

What is not specified is when to move it.

The kill-switch overview is explicit, and the wording repays reading closely:

the ≤ 10-min Tier-1 SOC activation owner assumes a staffed Security Operations Center available to receive the incident-commander order. For purely autonomous agents in 24/7 operation where no SOC is staffed off-hours (and the agent owner is the only human in the loop), the M3/M4 activation path requires automation that this v0.33.0 specification does not yet define.

So the documented activation path assumes a staffed SOC. The escalation path to M3 or M4 assumes a human incident commander reachable inside ten minutes, and where that assumption fails, the specification says so and stops. No signals, no thresholds, no policy for which mode to enter at what scope.

The hole sits exactly where the agent is most autonomous and the team is smallest. An organisation with a 24/7 SOC has the least need of an automatic trigger and matches the operating model the specification assumes. A two-person team running an agent unattended overnight has the most need and gets an acknowledged gap.

One smaller thing, on the same page: it describes itself as v0.33.0 while the current release is v0.35.0, and nothing has been pushed to the repository since 9 July. Version drift on the safety-controls page is the drift that costs most.

What the archive says about this problem

Darknet reviewed FIDO in 2016 — Netflix’s orchestration layer for automated incident response, evaluating and scoring malware detections. Its own capability list at the time read: “Enforcement – Currently work in progress (disable accounts, reset passwords, kill NIC etc).” Correlation and scoring were built. Acting on them was not. FIR arrived a year later with the case-management half.

Ten years on, AI IR Overlay lands on the same boundary from the other side. It supplies the containment contract and a working demonstration of it — the enforcement half FIDO left unfinished — and leaves the autonomous decision to adopters.

That continuity is the finding. Two projects, a decade apart, different problems, and both stop where a machine would have to decide on its own that something is wrong enough to act. The interface is the tractable part. The trigger is not, and naming it keeps the missing piece visible rather than implied.

For the offensive side, this doubles as a concrete definition of impact. We have covered PyRIT and mcp-scanner for exercising agent attack surfaces. Finding the prompt injection is the easy half. If the target cannot put the affected agent into read-only mode, cannot disable one high-risk tool without killing the service, and cannot export its retrieval and tool-call history afterwards, those are findings in their own right.

What teams can use today

Treat this as a planning and tabletop framework, not as proven operational containment. The maturity evidence is thin and the project does not hide it: one contributor, 479 commits, one star, no forks, no issues opened or closed, and no documented production incident. The end-to-end walkthrough in the repository is synthetic and labelled as such.

So run the exercises and do not report the maturity levels upward. Take one production agent, write down what it can actually write to, try to put it into read-only mode, and try to export six classes of evidence covering the last hour. Any of those three failing is a real gap in a real system.

And then ask the question the specification leaves open: if that agent misbehaves at three in the morning and nobody is watching, what moves it to M3? On present evidence the answer is a person who has not been woken up yet, and AI IR Overlay has not written down how to replace them.

You can read the specification here: https://github.com/jacobideji/aiiroverlay

Topics

  • Advertorial (28)
  • Apple (46)
  • Cloud Security (8)
  • Countermeasures (232)
  • Cryptography (86)
  • Dark Web (7)
  • Database Hacking (90)
  • Events/Cons (7)
  • Exploits/Vulnerabilities (433)
  • Forensics (64)
  • GenAI (14)
  • Hacker Culture (10)
  • Hacking News (238)
  • Hacking Tools (713)
  • Hardware Hacking (82)
  • Legal Issues (179)
  • Linux Hacking (74)
  • Malware (241)
  • Networking Hacking Tools (352)
  • Password Cracking Tools (106)
  • Phishing (41)
  • Privacy (218)
  • Secure Coding (119)
  • Security Software (235)
  • Site News (51)
    • Authors (6)
  • Social Engineering (37)
  • Spammers & Scammers (76)
  • Stupid E-mails (6)
  • Telecomms Hacking (6)
  • UNIX Hacking (6)
  • Virology (6)
  • Web Hacking (385)
  • Windows Hacking (171)
  • Wireless Hacking (45)

Security Blogs

  • Dancho Danchev
  • F-Secure Weblog
  • Google Online Security
  • Graham Cluley
  • Internet Storm Center
  • Krebs on Security
  • Schneier on Security
  • TaoSecurity
  • Troy Hunt

Security Links

  • Exploits Database
  • Linux Security
  • Register – Security
  • SANS
  • Sec Lists
  • US CERT
Advertisement

Footer

Most Viewed Posts

  • Brutus Password Cracker Hacker – Download brutus-aet2.zip AET2 (2,492,875)
  • Darknet – Hacking Tools, Hacker News & Cyber Security (2,175,256)
  • Top 15 Security Utilities & Download Hacking Tools (2,099,210)
  • 10 Best Security Live CD Distros (Pen-Test, Forensics & Recovery) (1,201,711)
  • Password List Download Best Word List – Most Common Passwords (936,122)
  • wwwhack 1.9 – wwwhack19.zip Web Hacking Software Free Download (778,852)
  • Hack Tools/Exploits (675,353)
  • Wep0ff – WEP Evil Twin Attack Tool (532,945)

Search

Recent Posts

  • http-terminator – AI-Assisted HTTP Request-Smuggling Discovery September 28, 2026
  • Hash Identifier Tools – Command-Line Password Hash Identification September 21, 2026
  • whitelist-bypass – WebRTC Tunnels Through Video-Calling Platforms September 15, 2026
  • WRAITH – Browser Hooking and Blind XSS Page Mirroring September 7, 2026
  • Praetorian – Offensive Security Tools Built Around Portable Go Workflows August 31, 2026
  • AI IR Overlay – Incident Response Specification for AI Agents August 28, 2026

Tags

apple botnets computer-security darknet Database Hacking ddos dos exploits fuzzing google hacking-networks hacking-websites hacking-windows hacking tool Information-Security information gathering Legal Issues malware microsoft network-security Network Hacking Password Cracking pen-testing penetration-testing Phishing Privacy Python scammers Security Security Software spam spammers sql-injection trojan trojans virus viruses vulnerabilities web-application-security web-security windows windows-security Windows Hacking worms XSS

Copyright © 1999–2026 Darknet All Rights Reserved · Privacy Policy